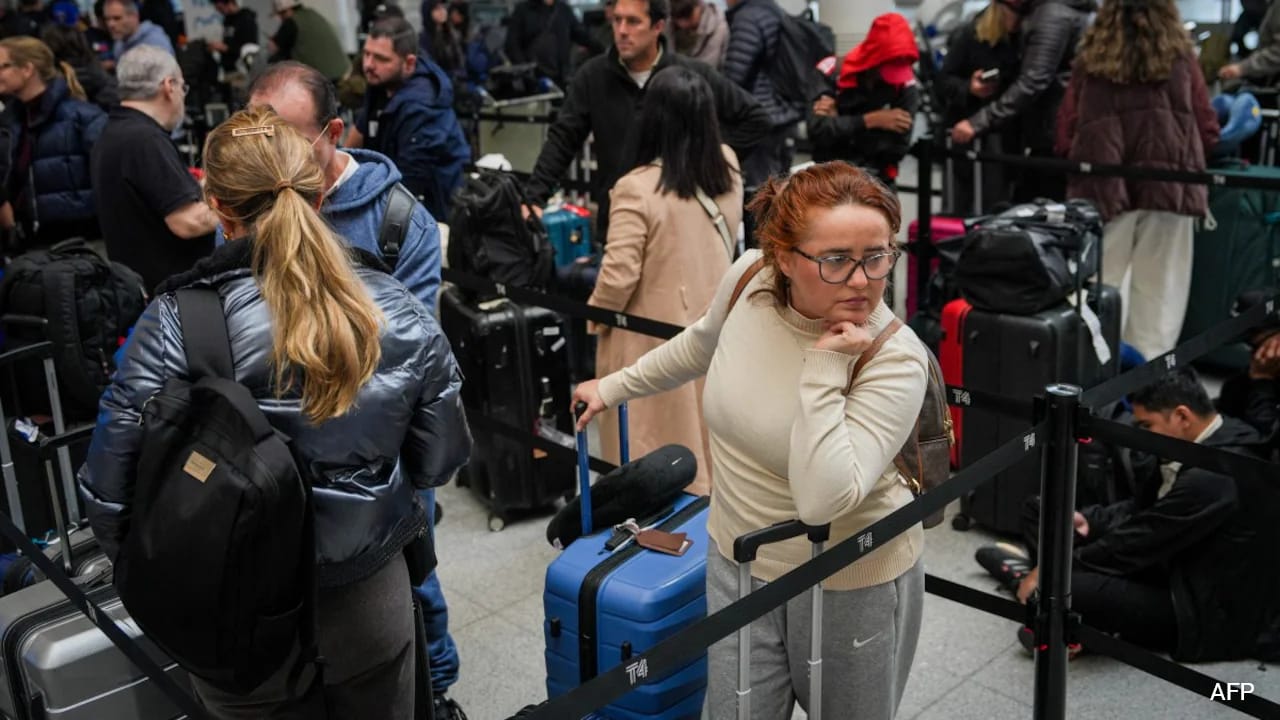
Flights grounded on runways. Bank ATMs frozen mid-transaction. Inbox screens dead across offices and homes. When a wave of disruptive US outages hits back to back, it's easy to assume a coordinated cyberattack is tearing through the country. Officials have pushed back on that theory, pointing instead to routine maintenance gone sideways, software bugs, and the sheer strain of slamming modern AI-driven fixes onto aging systems that were never designed for today's speed or load.
Honestly, the real story isn't that everything is failing at once. It's that our physical and digital backbones are stretched way past their comfort zones while everyone tries to patch the cracks at breakneck speed.
If you're trying to make sense of why US outages keep popping up across airlines, banking, cloud email, and the power grid, start with a simple truth. Much of America's core infrastructure is decades old, chronically under-maintained until something breaks, and now being pressured to absorb rapid AI-assisted updates while running at full tilt.
Why Aging Infrastructure and Rushed AI Fixes Collide
Picture trying to swap out a fuel pump on a classic car while driving 75 mph down a crowded highway. That's basically what happens when engineering teams push rushed software updates or security patches onto legacy systems that stay online around the clock.
As noted in reporting from NDTV and information science research from Cornell University's Steven Jackson, physical equipment and software don't live in neat little boxes. When a bug shows up or an AI tool spots a security flaw in minutes instead of weeks, teams face massive pressure to patch everything right away. Doing high-stakes maintenance under time pressure on tangled, older architecture makes accidental knock-on failures way more likely.
And that's only half the squeeze. Look at the physical side of the equation, especially electricity. Analysis from J.P. Morgan points out that large stretches of the US electric grid date back to the 1960s and 1970s, putting major assets right around the 60-year mark. Meanwhile, power demand is climbing faster than it did over the prior decade, driven by data centers, electric vehicles, heat pumps, and extreme weather.
The Hidden Cost of Cutting Human System Knowledge
Here's a mistake I see companies make all the time: treating software maintenance like a purely automated task and trimming the experienced engineers who actually know how the whole system fits together.
Case Western Reserve University professor Kalle Lyytinen has warned about this exact trap. AI tools can generate code fast or flag vulnerabilities quickly, sure. They don't naturally hold a deep mental map of how an entire legacy stack behaves when one piece changes. When companies cut seasoned staff and rely heavily on AI-generated fixes, fewer people on the team truly understand what the code is doing under the hood. When a weird edge case triggers a cascade, troubleshooting takes longer.
Concentrated Cloud Power Multiplies Small Glitches
Ever notice how a hiccup at one cloud provider can suddenly knock out tools you thought had nothing to do with each other?
A huge chunk of modern business software, email, and consumer services runs on a small handful of massive cloud platforms. Because so many organizations depend on the same underlying infrastructure, a single configuration error, maintenance slip, or software bug can ripple out to millions of people in minutes. Efficiency and scale are great on a calm day. When something breaks, concentration turns a local mistake into a national headache.
What Most People Get Wrong About Outages and AI
Myth 1. Every Sudden Outage Means a Hack
When flights stop moving or payment systems stall, "cyberattack" is usually the first word people reach for. Sometimes attackers do probe or disrupt systems. Often, though, the culprit is much less cinematic: a routine maintenance window that went wrong, a botched config change, or a software bug colliding with high traffic.
Knowing the difference matters. A cyberattack demands defense and containment; a maintenance bug demands better testing, staged rollouts, and sober engineering discipline.
Myth 2. AI Alone Will Rescue Fragile Systems
AI isn't a magic wand you wave over old hardware and brittle code. Yes, predictive models and machine learning can help utilities spot transformer anomalies, prioritize vegetation clearing around power lines, or forecast storm stress earlier. For example, EY highlighted work with Eversource Energy using predictive analytics and weather/grid data to help avoid tens of thousands of customer outages over a two-month stretch.
Still, software insights can't teleport a replacement transformer onto a substation pad overnight. Reporting from Utility Dive and Johns Hopkins University underscores how tight equipment supply chains are, with long waits for heavy turbines and looming transformer bottlenecks as AI data center loads grow. You can't "AI" your way past physical lead times and worn-out copper.
Myth 3. Preventive Spending Is Easy to Win Before a Crisis
Let's be real: nobody gets a parade for funding boring maintenance before something fails. Budgets are tight, political fights over taxes and spending drag on, and extreme weather keeps raising the baseline stress on aging gear. Waiting until equipment breaks is human nature—and expensive as hell once you factor in lost productivity, emergency repairs, and angry customers.
Practical Next Steps When Outages Hit
You can't rebuild a 1970s substation or rewrite an airline's legacy dispatch system before your morning coffee. You can tighten up how you operate and prepare right now.
- Build real redundancy into daily workflows. Don't put every critical file, login, or payment workflow behind a single cloud account or single digital channel. Keep offline copies of essential documents and a backup way to communicate or pay when card terminals or email go down.
- Stop rushing patches straight to production without testing. If you run technical systems, resist the panic to slam every AI-flagged fix straight into live environments. Stage changes, verify rollbacks, and keep human engineers who understand the architecture involved in reviews.
- Audit single points of failure before peak load. Check where your team or household depends on one vendor, one power circuit, or one internet line. Even small buffers—like a portable power station for home routers and medical gear, or clear fallback procedures at work—cut the sting when US outages strike.
- Separate noise from confirmed facts during an incident. Wait for official status updates rather than reacting to rumors on social media, and log what broke and how long it stayed down so you can fix real weak spots afterward.
Resilient systems don't come from flashy shortcuts or panicked patches. They come from steady maintenance, clear ownership, and respecting physical limits before the lights go out.